Grok, in plain English.
The model built into X had a busy few weeks. Here is what actually changed, and what the numbers in the announcements mean if you do not build this for a living.

What Grok is
Grok is the AI assistant made by xAI, Elon Musk’s AI company, and the one wired into X. It does the same broad job as ChatGPT or Claude — you ask, it answers — with one deliberate difference: it is plugged into what people are posting on X right now, so it leans on live public conversation rather than only on what it was trained on months ago.
That is the pitch, and it is also the catch. A model reading the internet as it happens inherits whatever the internet is saying that day, true or not.
What changed recently
Grok 4.7 is the current flagship, replacing 4.6 which arrived in August. The pitch is coding, agentic work and fewer made-up answers.
It got faster. Musk announced speed improvements on 1 October.
It turned up somewhere unexpected — reportedly available through Google’s enterprise agent platform, which means companies can use it without being inside X’s world at all. Rivals selling each other’s models is the genuinely new part.
Grok 5 is not out. As of September it was still training, whatever the speculation says.
Treat version numbers lightly. The gap between 4.6 and 4.7 is not the gap between a car and a better car — it is mostly tuning, and every lab now ships these increments every few weeks.
The one number worth understanding
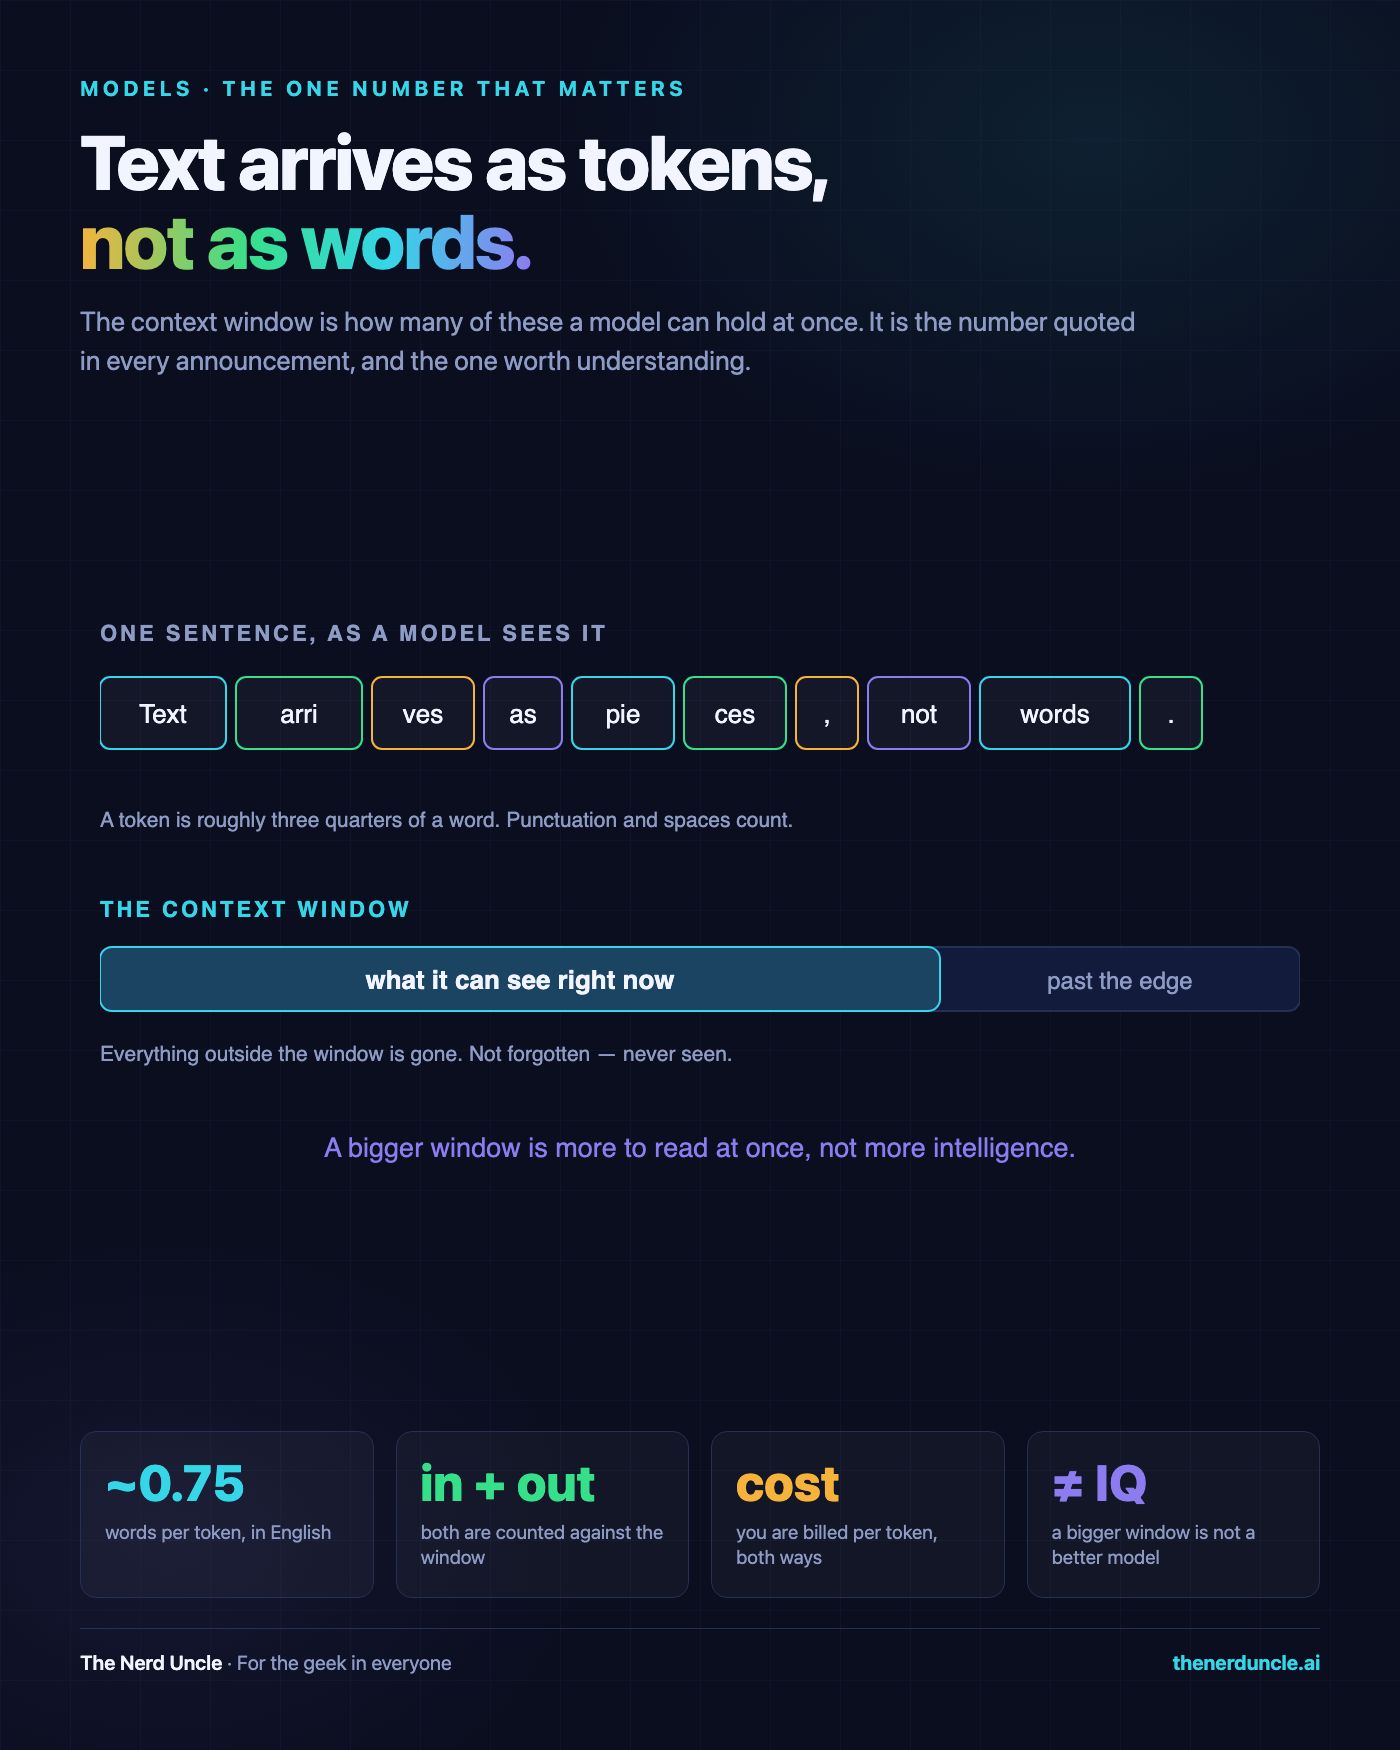
Every announcement quotes a context window. Grok 4.7’s is 500,000 tokens. A token is roughly three quarters of a word, so that is somewhere around a thousand pages.
Here is the thing people get wrong: that is not how much the model knows. It is how much it can hold in mind at once — the size of the desk, not the size of the library. Fill the desk with your contract, your emails and last year’s invoices and it can reason across all of it in one go. Close the conversation and the desk is cleared.
And “agentic tool calling”?
It means the model is allowed to do things rather than only describe them — run a search, call a system, read a file, then use what came back. That is the same loop behind coding assistants, and the same loop behind anything in operations that actually commits a decision rather than suggesting one.
It is also where the care goes. A model that can only talk is wrong in a conversation. A model that can act is wrong in your systems — which is why the question worth asking a vendor is never what it can do, but what it will refuse to do.