What a GPU actually does.
Why the chips built to draw video games ended up running artificial intelligence — explained without a single equation.

Two different shapes of chip
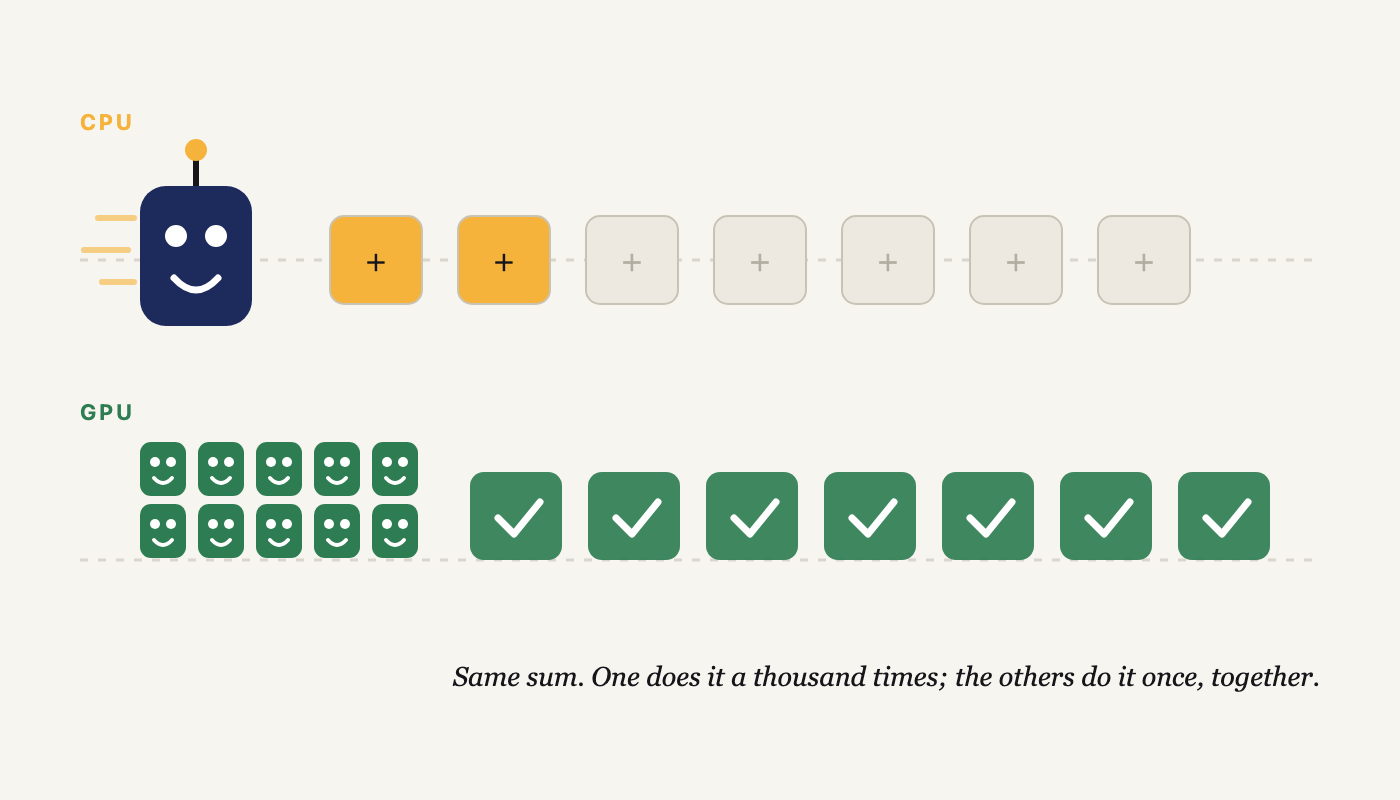
A CPU has a handful of very fast cores. Give it a complicated job with lots of if this, then that and it is superb. A GPU has thousands of much simpler ones. Give it the same small sum to do a million times over and it will finish while the CPU is still rolling its sleeves up.
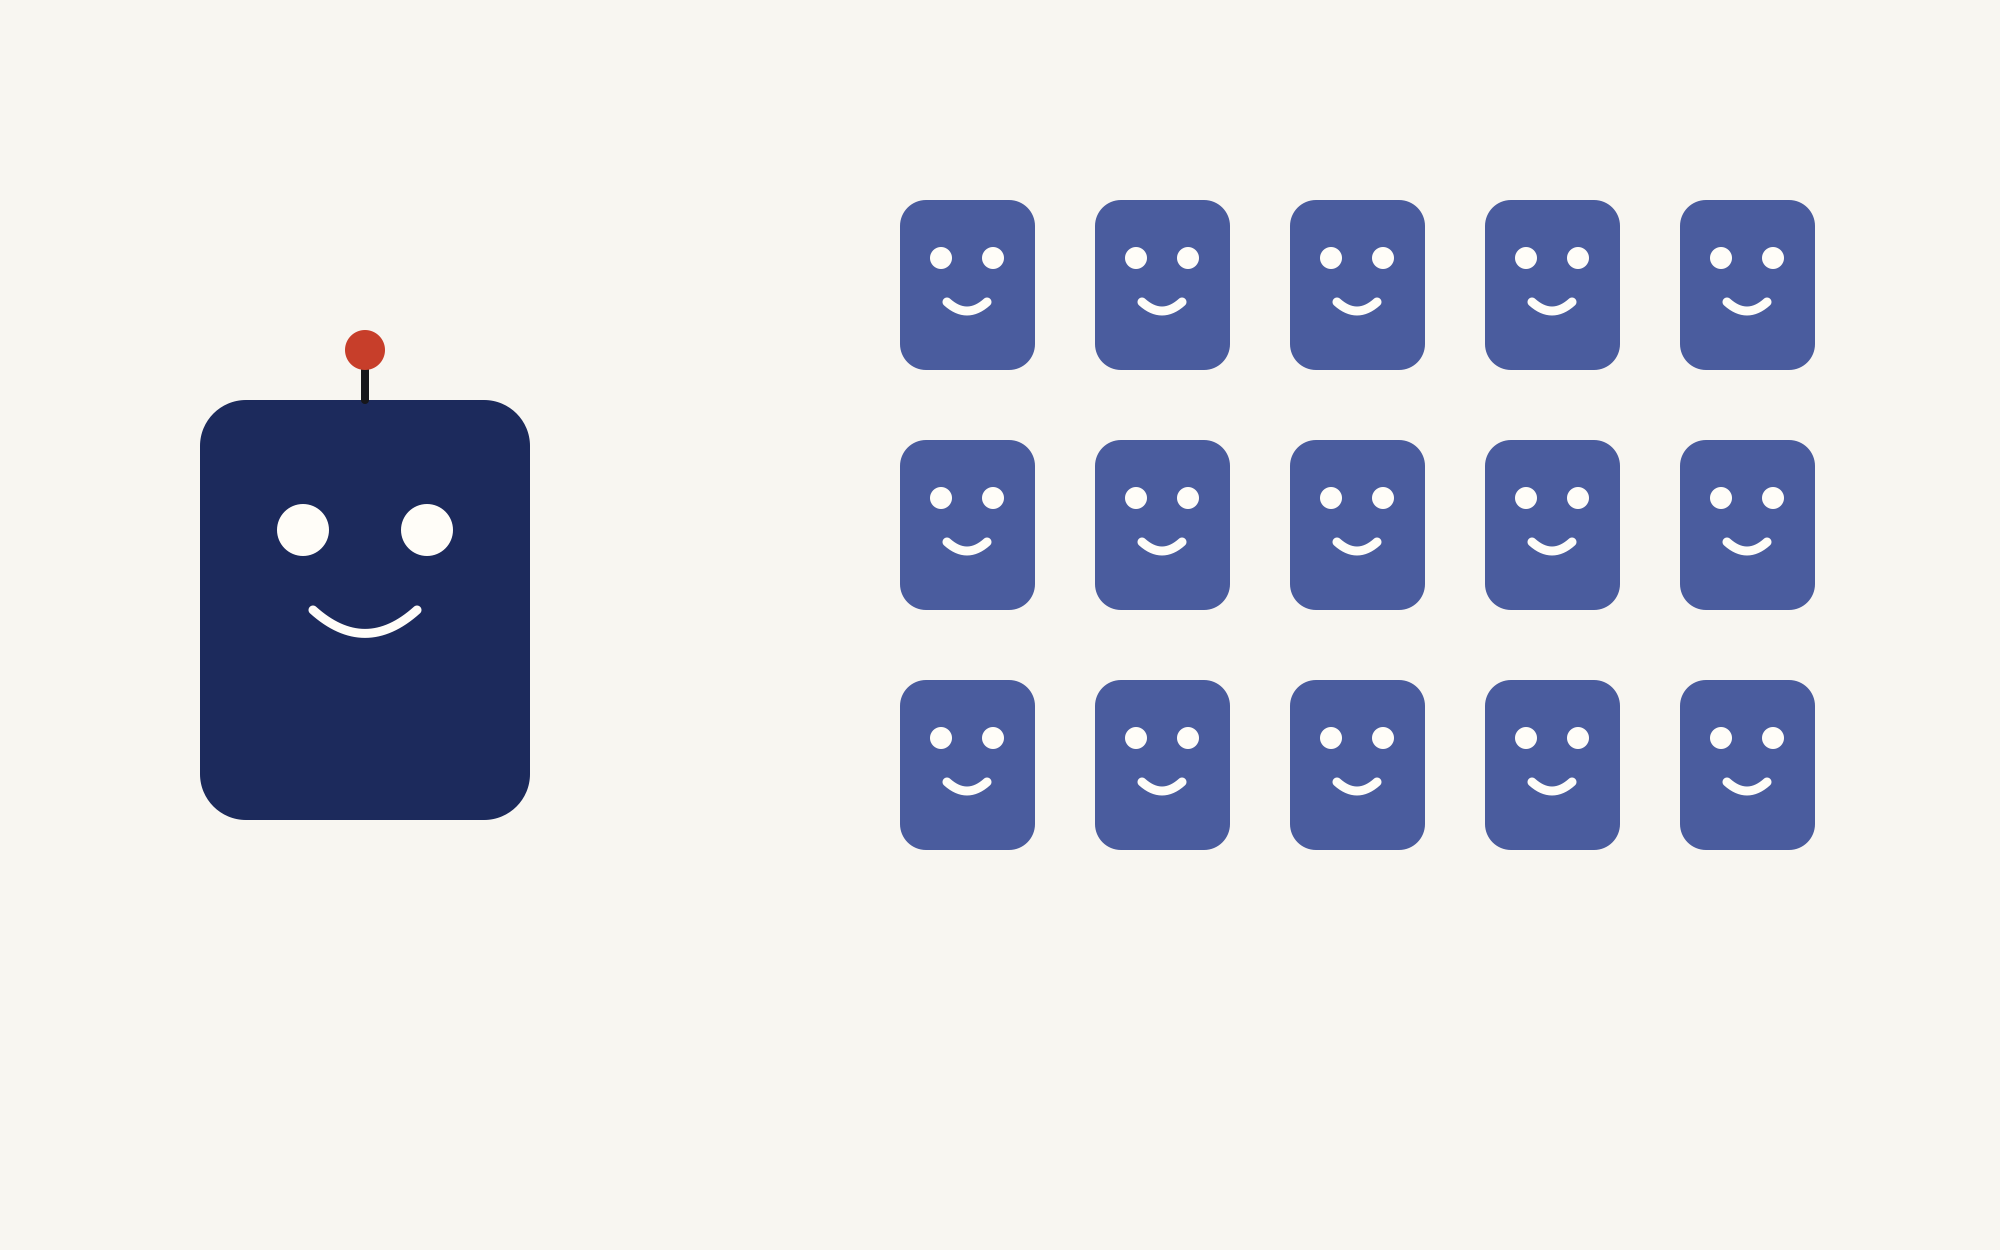
That is the entire difference. Not better or worse — a different shape, for a different kind of work.
Why AI is exactly that kind of work
Underneath the conversation, a language model is doing one thing over and over: multiplying long lists of numbers together and adding up the results. Billions of times, for every answer. No branching, no cleverness — the same small sum, endlessly.
Which is the job a GPU was already built for. Drawing a frame of a game means working out a colour for two million pixels at once. Running a model means working out a number for billions of weights at once. The chip could not care less which one you asked for.
Why they need so many
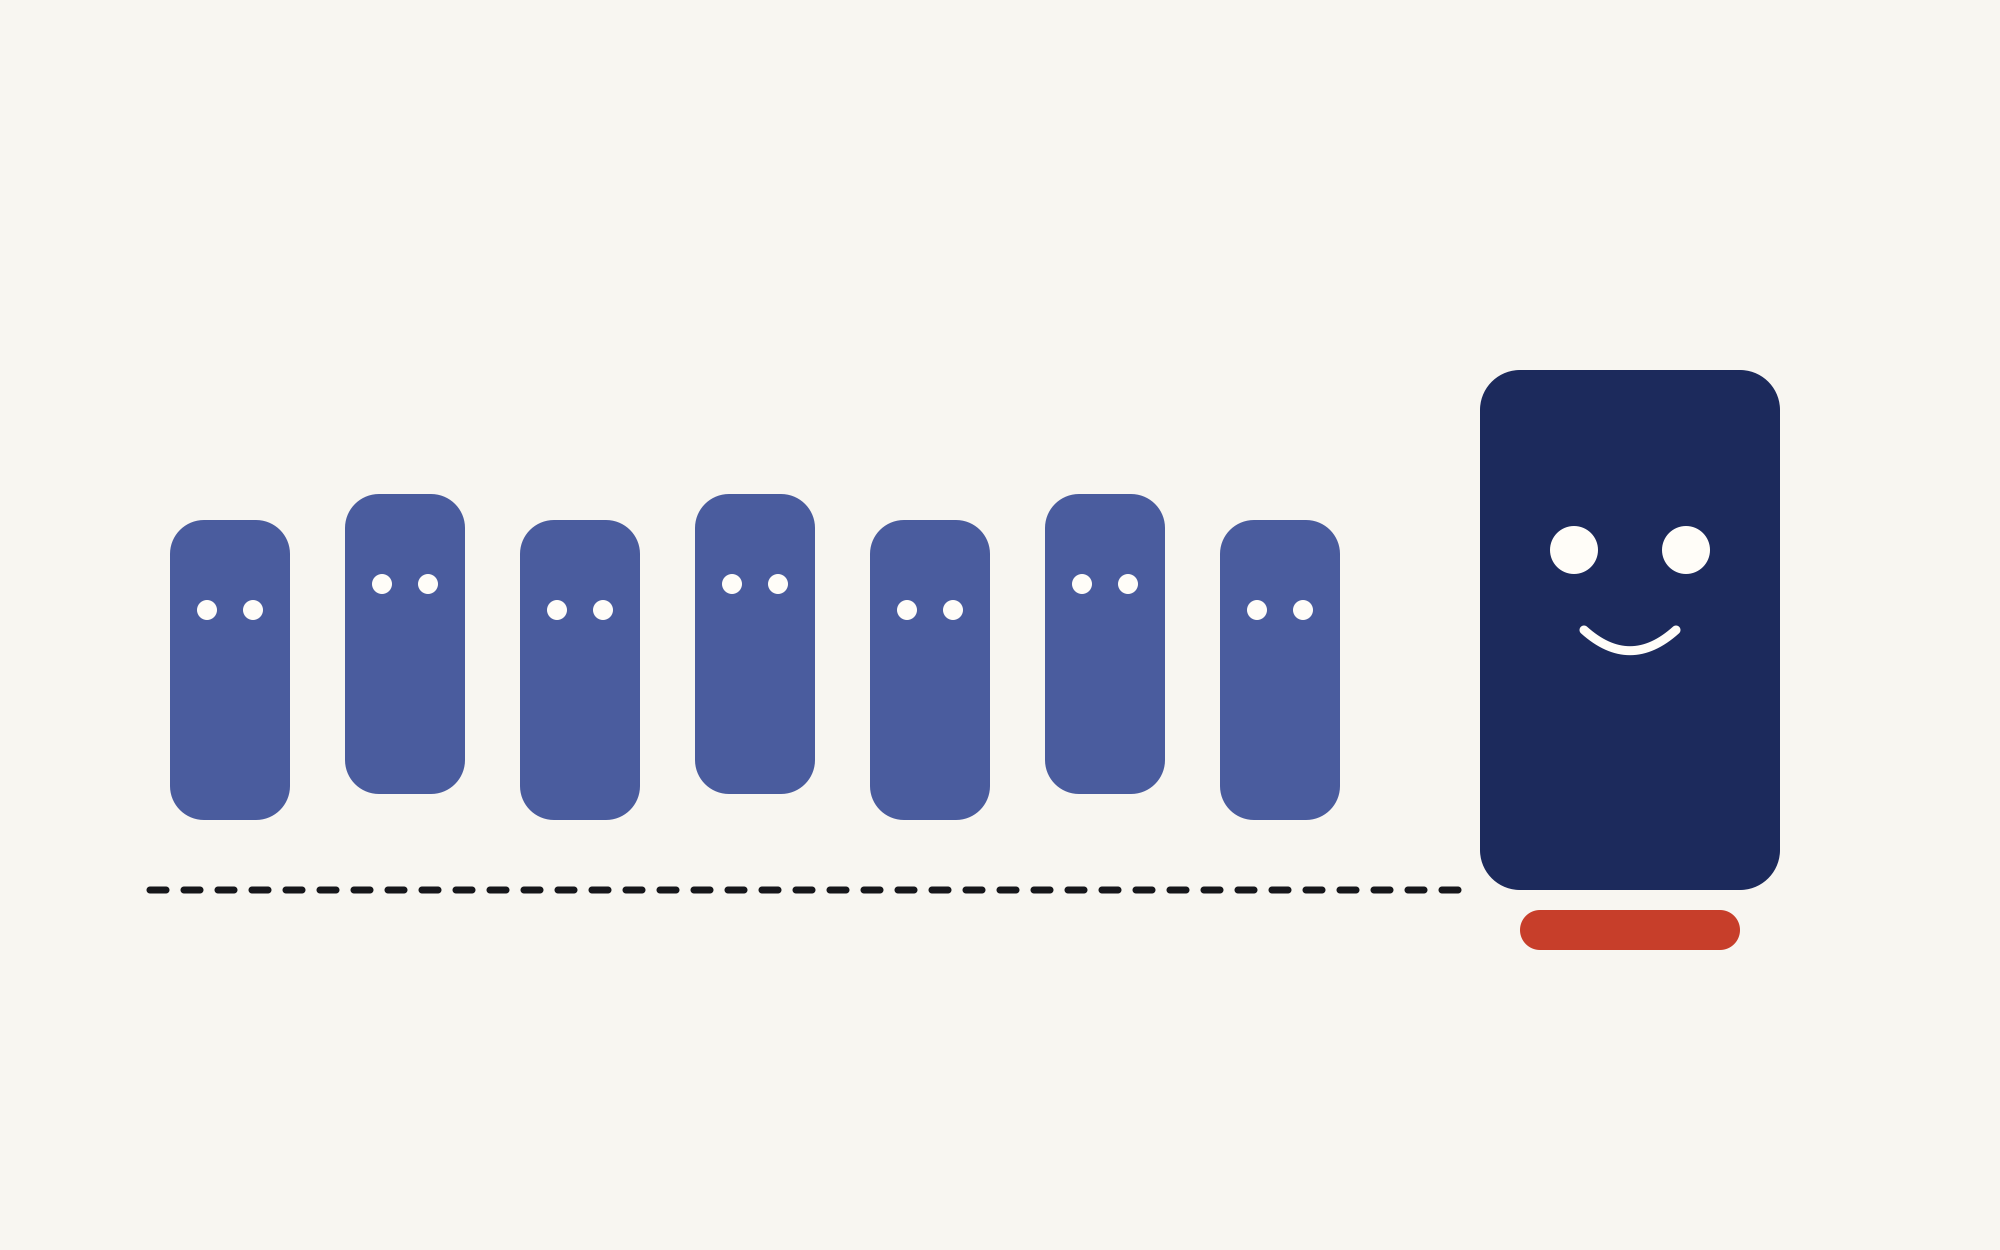
A large model does not fit on one card. The weights alone run to hundreds of gigabytes, so the model is split across several GPUs that have to talk to each other constantly — which is why the cable between them matters as much as the chips.
And the expensive part is not the sum, it is fetching the numbers to do it with. Most of the effort in making models fast goes into moving less data, not into doing less arithmetic.
What it means if you are buying, not building
You are renting time on a queue. Most of the wait for an answer is waiting for a turn, not the model thinking.
Bigger is not automatically better. A smaller model that answers in a second often beats a larger one that takes thirty, for the same job.
Where it runs is a real decision. Some answers can afford a trip to a data centre. A barrier opening for a lorry cannot.